Qwen3.8-27B Drops Apache Multimodal Weights — the Workstation Companion to Max
Alibaba’s Qwen team posted Qwen3.8-27B on Hugging Face — a 27-billion-parameter native vision-language dense model with 262K context (extensible to 1M), thinking mode by default, and Apache 2.0 weights — the local companion to July’s 2.4T Qwen3.8-Max preview. Vendor SWE-bench Pro 61.7 is lab-run.

Corrected October 14, 2026: Marked SWE-bench Pro and OSWorld figures as vendor-run with harness differences, removed an unsupported characterization of the Max preview, and turned an internal reference into a link.
The 2.4T Max preview was a datacenter artifact. 27B Apache multimodal is what actually runs on a workstation next to Muse Glimmer 30B (Aug 10). Its SWE-Pro / OSWorld numbers are vendor-run, with harness settings that differ from rivals’.
Alibaba’s Qwen team released Qwen3.8-27B weights at Qwen/Qwen3.8-27B. The checkpoint is a 27B dense native vision-language model (images and video), Apache 2.0, 262,144 native context (YaRN to 1,000,000). Thinking mode is on by default, with reasoning_effort at xhigh / medium / low. It follows Qwen3.8-Max-Preview (2.4T), previewed July 19.
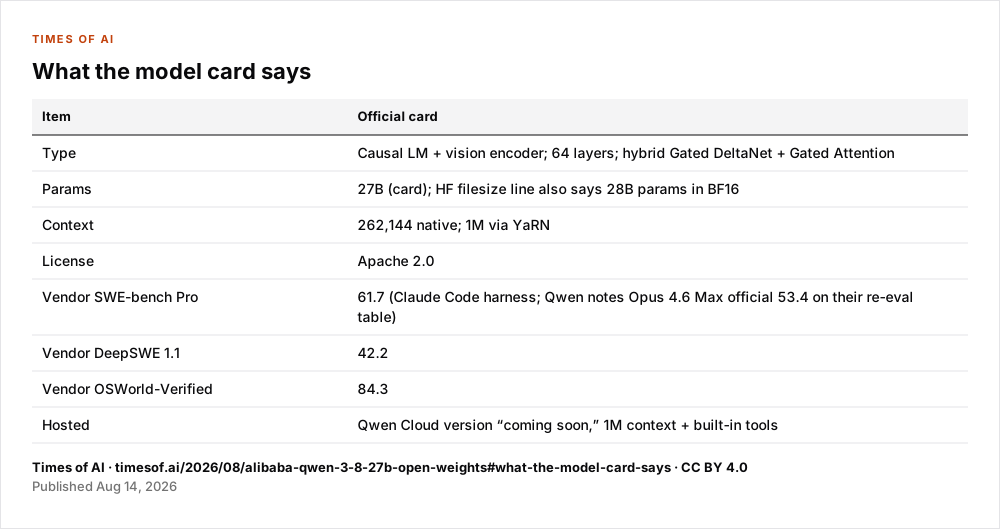
What the model card says#
| Item | Official card |
|---|---|
| Type | Causal LM + vision encoder; 64 layers; hybrid Gated DeltaNet + Gated Attention |
| Params | 27B (card); HF filesize line also says 28B params in BF16 |
| Context | 262,144 native; 1M via YaRN |
| License | Apache 2.0 |
| Vendor SWE-bench Pro | 61.7 (Claude Code harness; Qwen notes Opus 4.6 Max official 53.4 on their re-eval table) |
| Vendor DeepSWE 1.1 | 42.2 |
| Vendor OSWorld-Verified | 84.3 |
| Hosted | Qwen Cloud version “coming soon,” 1M context + built-in tools |
Qwen’s table is lab-run. Several rows use in-house benches (QwenSWEBench, CoWorkBench, RecreationBench). Treat 61.7 SWE-bench Pro as vendor-claimed until independent boards replicate.
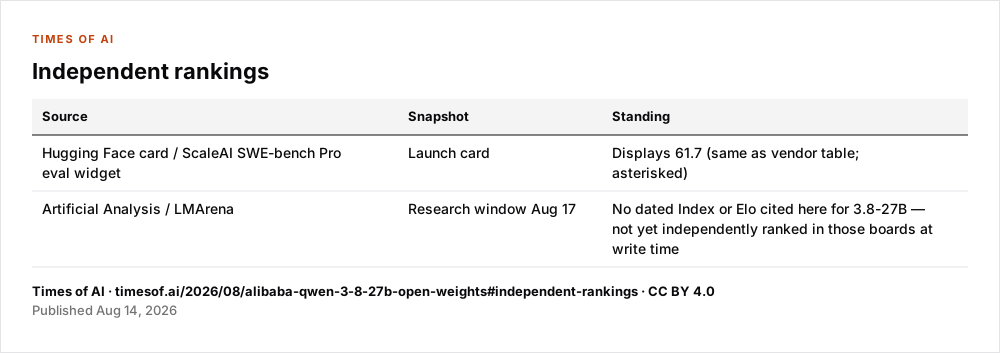
Independent rankings#
| Source | Snapshot | Standing |
|---|---|---|
| Hugging Face card / ScaleAI SWE-bench Pro eval widget | Launch card | Displays 61.7 (same as vendor table; asterisked) |
| Artificial Analysis / LMArena | Research window Aug 17 | No dated Index or Elo cited here for 3.8-27B — not yet independently ranked in those boards at write time |
Limits#
- Vendor benches are lab-run; several use in-house harnesses.
- No Artificial Analysis Index or LMArena Elo at write time.
- Whether Max weights follow or stay API-only is open.
Sources#
- Hugging Face: Qwen/Qwen3.8-27B (Apache 2.0)
- Qwen blog citation on the card: qwen.ai/blog?id=qwen3.8
- Times of AI: Qwen3.8-Max preview (July 19, 2026) — Max preview, not this weight drop
- MarkTechPost: Alibaba Previews Qwen3.8-Max, a 2.4 Trillion-Parameter Multimodal Model (July 19, 2026)