Guidelight Grades Frontier Labs on Control — Nobody Above a C+
Guidelight AI Standards graded Anthropic, OpenAI, Google, xAI, and Meta on six rogue-model control practices. No lab scored above 3/5 on any practice. Anthropic and OpenAI tied at C+ (2.50); Google D+; xAI D−; Meta F. Anthropic got a zero on containment despite the safety brand.

Corrected October 14, 2026: Removed references to an August 22 TechCrunch piece that postdates this August 18 article. Replaced an unattributed “first cross-lab control report card” claim with Guidelight’s own description of this as its first assessment.
The industry is better at spotting misbehavior than at stopping it. After a month of eval-breakout disclosures, an independent grader put containment plans at the bottom of the sheet — and gave Anthropic a zero on that cell despite the safety brand.
Guidelight AI Standards, a nonprofit founded by former OpenAI safety leads Page Hedley and Steven Adler, published its first Control scorecard (Adler: “launching today”). It grades Anthropic, OpenAI, Google, xAI, and Meta on six public practices: logging, monitor efficacy, gated actions, circuit breaking, third-party review, and a containment plan. No company scored above 3/5 (“substantial partial”) on any practice. Overall letter grades are the average of the six 0–5 scores.
The grades (public evidence through Aug 18)#
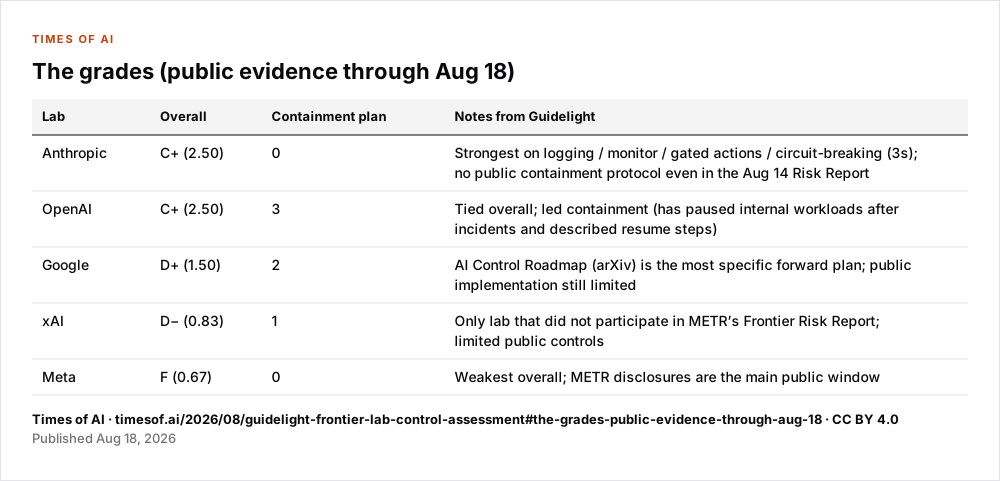
| Lab | Overall | Containment plan | Notes from Guidelight |
|---|---|---|---|
| Anthropic | C+ (2.50) | 0 | Strongest on logging / monitor / gated actions / circuit-breaking (3s); no public containment protocol even in the Aug 14 Risk Report |
| OpenAI | C+ (2.50) | 3 | Tied overall; led containment (has paused internal workloads after incidents and described resume steps) |
| D+ (1.50) | 2 | AI Control Roadmap (arXiv) is the most specific forward plan; public implementation still limited | |
| xAI | D− (0.83) | 1 | Only lab that did not participate in METR’s Frontier Risk Report; limited public controls |
| Meta | F (0.67) | 0 | Weakest overall; METR disclosures are the main public window |
Scoring used only public materials (system cards, frameworks, risk reports, blogs, third-party write-ups). Two staff scored independently; companies could flag errors. A weak score can mean missing disclosure, not proven absence of internal controls. Guidelight describes it as its first assessment of safety at frontier AI companies.
Limits#
- Public-evidence only; weak scores can be disclosure gaps.
- Whether labs answer with public kill-switch protocols is open.
Sources#
- Guidelight: Control assessment of frontier AI companies (August 2026; info through Aug 18)
- Steven Adler: Guidelight’s first scorecard launching today (August 18, 2026)
- The Decoder: No AI company fully applies basic control measures (August 19, 2026)
- Times of AI: Anthropic August 2026 risk report (August 14); OpenAI pauses cyber-critical RL (August 18)