Muse Code Co-Trains the Harness — Spark 1.2 Alone Is Incomplete
Meta shipped Muse Code beta, a terminal coding agent with persistent background subagents and a replay-exact event log, powered by Muse Spark 1.2. Lab coding benches lead the post.

Corrected October 14, 2026: Removed an undated Arena Elo figure and unverified Artificial Analysis scores and comparisons; the summary now says lab coding benchmarks lead the post.
Meta is no longer only shipping chat/multimodal Muse — it is competing in the terminal agent market where Anthropic (Claude Code), OpenAI (Codex / ChatGPT Work), and Cursor-class tools already live. Co-training model + harness is the real product thesis: Spark 1.2 without Muse Code is incomplete.
Meta shipped Muse Code (beta) — a terminal coding agent — powered by Muse Spark 1.2, the newest Muse Spark tier. Install path: curl -fsSL https://dev.meta.ai/install.sh | bash (macOS/Linux). Muse Spark 1.2 is available in Muse Code and Meta Model API with expanded global access. The stack targets long-horizon multi-file / whole-repo engineering.
What shipped#
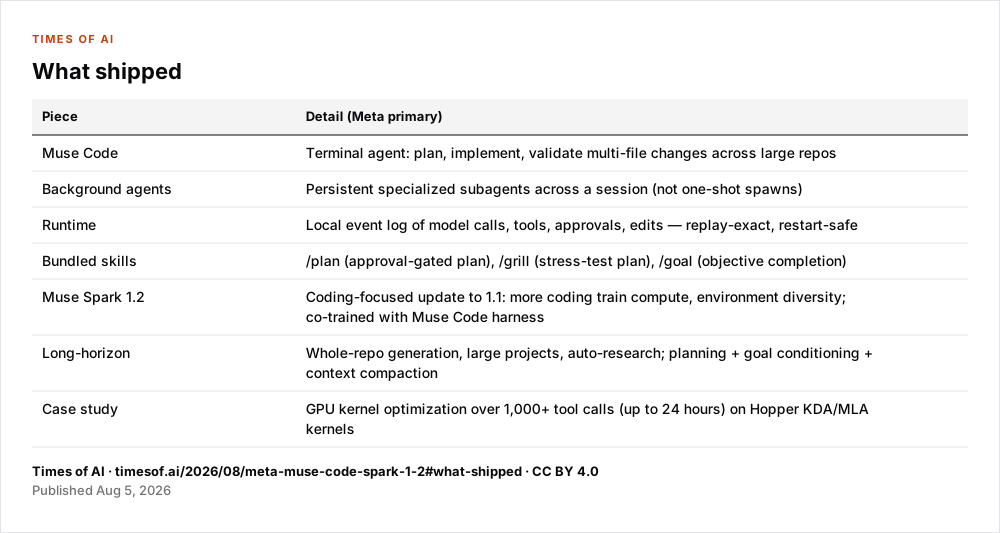
| Piece | Detail (Meta primary) |
|---|---|
| Muse Code | Terminal agent: plan, implement, validate multi-file changes across large repos |
| Background agents | Persistent specialized subagents across a session (not one-shot spawns) |
| Runtime | Local event log of model calls, tools, approvals, edits — replay-exact, restart-safe |
| Bundled skills | /plan (approval-gated plan), /grill (stress-test plan), /goal (objective completion) |
| Muse Spark 1.2 | Coding-focused update to 1.1: more coding train compute, environment diversity; co-trained with Muse Code harness |
| Long-horizon | Whole-repo generation, large projects, auto-research; planning + goal conditioning + context compaction |
| Case study | GPU kernel optimization over 1,000+ tool calls (up to 24 hours) on Hopper KDA/MLA kernels |
Meta frames 1.2 as an interim step “toward the frontier, with larger and much more capable models on the way.”
Claims vs checks#
Lab-reported: Meta publishes Terminal-Bench 2.1, DeepSWE 1.1, and internal coding-bench charts on the launch post (see methodology report linked from the blog). Kernel case studies claim progressive speedups vs. baseline Triton/PyTorch references under tool-call budgets.
Independent (as available near launch):
- Artificial Analysis: no dated 1.2-specific Intelligence Index result was checked for this article.
Limits#
- If Arena votes for 1.2 are thin in the first days, rank is not settled.
- 1.2-specific full AA Index may lag the launch post.
- API pricing/rate limits and “larger models on the way” remain open.