Groq 3 LPX Enters Full Production — AA Hit 3,431 tok/s on Nvidia’s Own Gear
Nvidia put Groq 3 LPX — the interactive inference accelerator that extends Vera Rubin — into full production. Artificial Analysis measured 3,431 output tokens per second on Gemma 4 31B at 100K context on a private Nvidia-hosted endpoint. Nebius is the first named cloud; Groq will follow with Dell. The 3,431 figure is AA's measurement on Nvidia-hosted hardware, not a worldwide production-API record.

Corrected October 14, 2026: Attributed Groq's early-adopter and Dell plans to Groq's blog, and corrected the CNBC 'later this year' timeline, which refers to the racks at Nebius.
Nvidia is productizing its Groq licensing deal (reported at ~$20B) as a rack in full production, sitting next to Rubin GPUs rather than replacing them. Token generation — not prefill — is the agent bottleneck; 256 SRAM LPUs are the bet that GPUs stay busy while agents stay snappy.
NVIDIA newsroom: NVIDIA Groq 3 LPX, the interactive AI inference accelerator that extends Vera Rubin NVL72, is in full production. Artificial Analysis ran its 100K-context suite on Gemma 4 31B against an LPX system in Nvidia’s own data centers and recorded 3,431 output tokens/second (newsroom rounds to 3,400; 4× the nearest alternative in Nvidia’s comparison). Nebius is the first AI cloud (Token Factory, same API). Groq (the inference-cloud company) said in a blog post it will be among the first adopters, working with Dell to deploy. Product page: 256 interconnected LPU / LP30 accelerators per LPX rack.
What shipped#
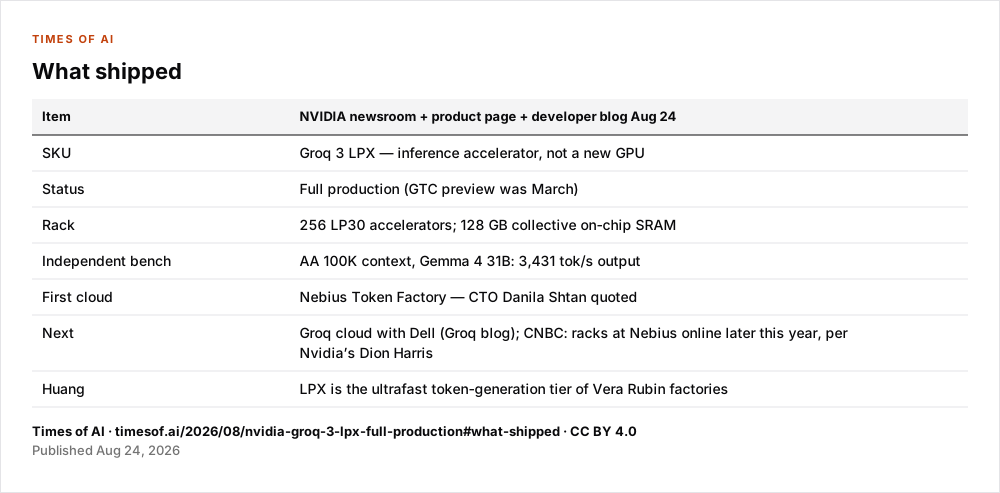
| Item | NVIDIA newsroom + product page + developer blog Aug 24 |
|---|---|
| SKU | Groq 3 LPX — inference accelerator, not a new GPU |
| Status | Full production (GTC preview was March) |
| Rack | 256 LP30 accelerators; 128 GB collective on-chip SRAM |
| Independent bench | AA 100K context, Gemma 4 31B: 3,431 tok/s output |
| First cloud | Nebius Token Factory — CTO Danila Shtan quoted |
| Next | Groq cloud with Dell (Groq blog); CNBC: racks at Nebius online later this year, per Nvidia’s Dion Harris |
| Huang | LPX is the ultrafast token-generation tier of Vera Rubin factories |
Same-day NVIDIA technical blogs describe the LPX/Rubin pairing; they are not a second SKU.
Caveat on the AA number: the developer blog is explicit that AA hit a private Nvidia-hosted endpoint. StorageReview and others note competing 870 tok/s-class figures are live public endpoints. The 3,431 figure is AA's measurement on Nvidia-hosted hardware, not a worldwide production-API record.
Vera CPU × xAI is a different SKU the same day.
Limits#
- 3,431 tok/s is AA on a private Nvidia-hosted endpoint — not a public production-API record.
- Nebius Token Factory lighting schedule and whether AA re-runs on a public endpoint are open.
- Vendor AgentX 30× claims are Nvidia’s, not independent.
Sources#
- NVIDIA: Groq 3 LPX Now in Full Production With World-Class Speed for Agentic AI (August 24, 2026)
- NVIDIA Groq 3 LPX product page
- NVIDIA Technical Blog: How Groq 3 LPX Unlocks Ultrafast Interactivity (August 24, 2026) — AA 3,431 tok/s
- Groq: Among the First to Bring NVIDIA Groq 3 LPX and Vera Rubin NVL72 to Market (August 24, 2026)
- CNBC: Nvidia says Groq racks will be online this year (August 24, 2026)
- The Next Web: Nvidia pays Poolside $6bn to license its model factory and hire 109 staff