ChatGPT Updates Paid Sol and Schedules Unlimited Free/Go Luna Text
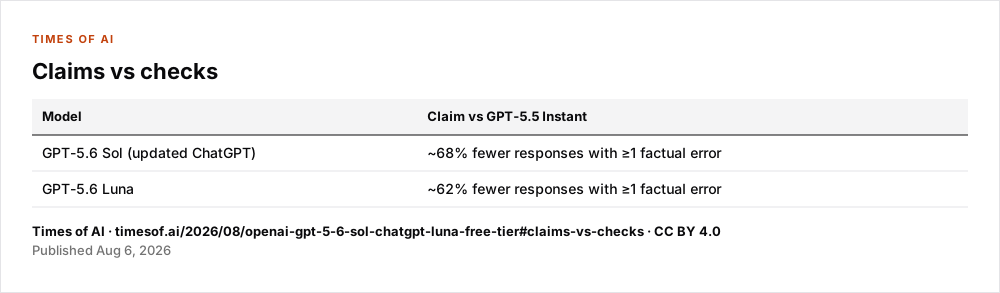
OpenAI retuned GPT-5.6 Sol for ChatGPT Plus/Pro with a thinking-effort slider and scheduled Luna as the Free/Go default, with unlimited text chats the following week. Internal evals claim ~68% / ~62% fewer factual-error responses vs GPT-5.5 Instant — company-run, not Arena or Artificial Analysis. Distribution day, not a new base-model family.

OpenAI updated Sol for Plus/Pro and scheduled a broader Luna text allowance for Free/Go. Unlimited Luna text was planned for the following week; paid users received the new thinking-effort slider at announcement.
OpenAI updated ChatGPT defaults across paid and free tiers. Plus and Pro get a ChatGPT-tuned GPT-5.6 Sol (separate from the Sol used in Codex / ChatGPT Work) plus a thinking-effort slider that replaces separate Instant vs Thinking modes. Free and Go were scheduled to get GPT-5.6 Luna as default that week, with unlimited text chats and a Think button planned for the following week. OpenAI says one billion people now use ChatGPT weekly.
What changed by tier#
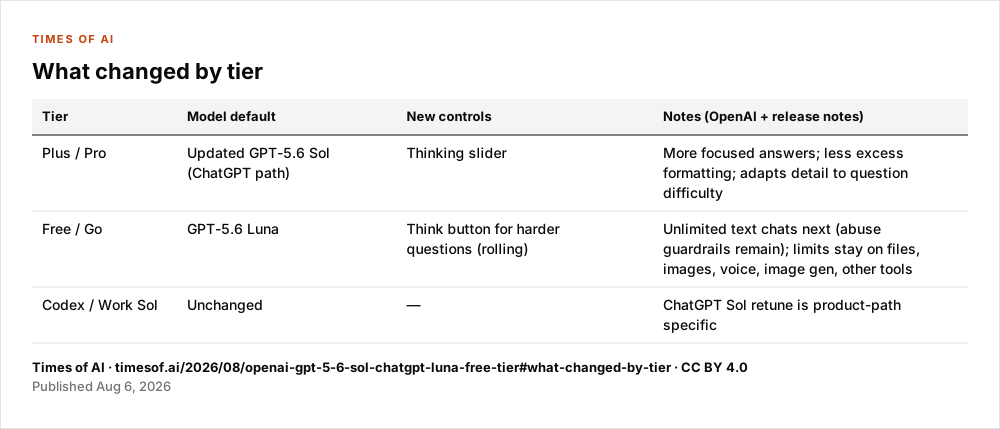
| Tier | Model default | New controls | Notes (OpenAI + release notes) |
|---|---|---|---|
| Plus / Pro | Updated GPT-5.6 Sol (ChatGPT path) | Thinking slider | More focused answers; less excess formatting; adapts detail to question difficulty |
| Free / Go | GPT-5.6 Luna | Think button for harder questions (rolling) | Unlimited text chats next (abuse guardrails remain); limits stay on files, images, voice, image gen, other tools |
| Codex / Work Sol | Unchanged | — | ChatGPT Sol retune is product-path specific |
Claims vs checks#
OpenAI reports an internal evaluation on finance, medicine, and law prompts requiring factual detail:
| Model | Claim vs GPT-5.5 Instant |
|---|---|
| GPT-5.6 Sol (updated ChatGPT) | ~68% fewer responses with ≥1 factual error |
| GPT-5.6 Luna | ~62% fewer responses with ≥1 factual error |
These are company-run figures — not independent arena or third-party factuality boards. Treat as lab-reported until Artificial Analysis / Arena-style audits catch up.
This is a ChatGPT product-path update. OpenAI says the Sol version powering Work and Codex is unchanged. The launch’s internal factuality evaluation does not establish a new public leaderboard result.
Limits#
- Factuality cuts are internal only; no new public Elo.
- Unlimited free text may raise abuse/cost pressure — not measured here.
- Work/Codex Sol stays deliberately different from chat Sol.
Correction (October 14, 2026): Clarified that Free/Go unlimited text and the Think button were scheduled for the following week, and removed unsupported claims about historical rankings carrying over.