xAI’s Grok 4.6 Table Shows a Sol Tie at $2/$6 Token Pricing
xAI released Grok 4.6 for agents and coding at $2/$6 per million tokens. Its launch table reports an AA Intelligence Index tie with GPT-5.6 Sol at 61 while trailing Sol/Fable on DeepSWE and Terminal-Bench; this account has not independently reproduced the comparisons.

At $2/$6, reporting a Sol tie on the AA composite in its launch table is a direct shot at OpenAI and Anthropic list prices. Read 4.6 as a price–agent step that ties Sol on AA without owning DeepSWE or Terminal-Bench.
xAI released Grok 4.6, an update that builds on Grok 4.5 with a longer supplemental training run. The lab positions it for long-running agents, coding, and more ambitious interactive/visual projects. On xAI’s published table it matches GPT-5.6 Sol Max at 61 on the Artificial Analysis Intelligence Index (Grok 4.5 High was 56; Fable 5 Max is 62). Pricing stays $2 / $6 per million input/output tokens, with a fast variant at 2× that price. Access: Cursor, Grok Build (2× included usage for the first week), the xAI API, plus OpenRouter, Vercel, and Cloudflare.
What xAI announced#
From the primary “Introducing Grok 4.6” post (x.ai/news/grok-4-6):
- Training: Longer supplemental run than 4.5; Grok 4.5 regenerated SFT trajectories across reasoning efforts and agent harnesses; RL on knowledge work, general coding, and domain environments (kernel optimization, web development, CAD).
- Behavior: Stronger first passes on visual/interactive apps; more self-testing before moving on in long trajectories.
- Safety: Wider pre-deployment suite and third-party testing.
Lab-cited evals (Grok 4.6 High vs named peers)#
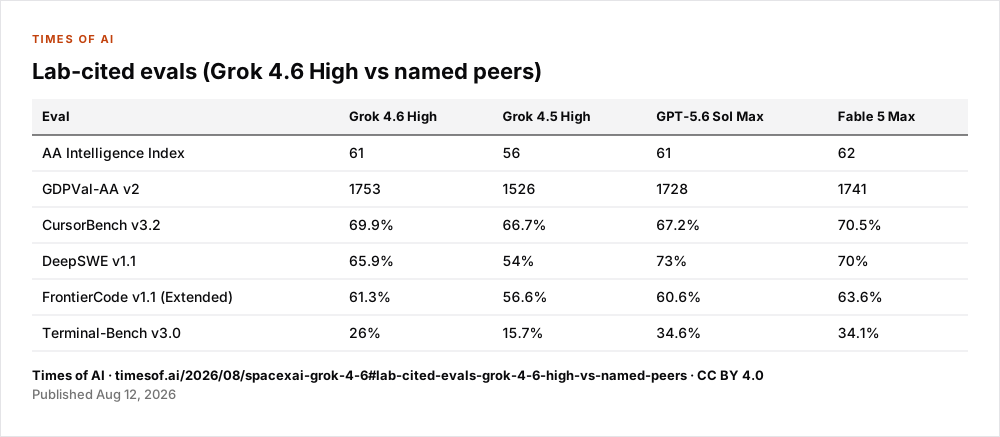
| Eval | Grok 4.6 High | Grok 4.5 High | GPT-5.6 Sol Max | Fable 5 Max |
|---|---|---|---|---|
| AA Intelligence Index | 61 | 56 | 61 | 62 |
| GDPVal-AA v2 | 1753 | 1526 | 1728 | 1741 |
| CursorBench v3.2 | 69.9% | 66.7% | 67.2% | 70.5% |
| DeepSWE v1.1 | 65.9% | 54% | 73% | 70% |
| FrontierCode v1.1 (Extended) | 61.3% | 56.6% | 60.6% | 63.6% |
| Terminal-Bench v3.0 | 26% | 15.7% | 34.6% | 34.1% |
xAI notes competitor figures are the best of self-reported or public leaderboard scores. DeepSWE and Terminal-Bench still trail Sol/Fable; the intelligence-index tie with Sol is reported in the vendor’s comparison table.
Claims vs checks#
The table above comes from xAI. Its peer figures combine developers’ self-reports and public results, so unknown harness or effort differences limit direct comparisons. No separately inspected historical AA or Arena snapshot is claimed here.
Limits#
- No dated LMArena Elo in the primary.
- DeepSWE and Terminal-Bench still trail Sol/Fable on the lab’s own table.
- Fast variant at 2× price; usage pattern not yet public.
Correction (October 14, 2026): Kept AA comparisons explicitly attributed to the vendor table and removed the unsupported claim that this review independently verified a dated ranking.