Update: Reflection Shows Beam — 501B / 23B Active, Apache 2.0 Weights Later This Month
Reflection published Beam on Oct. 5: a 501-billion-parameter sparse MoE (23B active) open-weight text model it says approaches GLM-5.2 on coding and reasoning with 3–4× less estimated inference compute. Weights, a technical report and a model card are promised later this month under Apache 2.0. Benchmarks are Reflection’s own; Kimi K3 and GLM-5.3 still lead on most shared tasks.

Corrected October 14, 2026: Removed claims that Beam was not on Artificial Analysis and an unsupported 'most serious U.S. attempt yet' superlative; noted that the comparison table is vendor-compiled.
Updated October 6, 2026: Reflection showed its cards. On October 5 the company published Beam — confirming the Axios scoop that sources said an open-weight release was “soon,” without a name, size, license or date.
Reflection AI’s first open-weight model is a sparse mixture-of-experts text system: 501 billion total parameters, 23 billion active, pretrained on 23.8 trillion tokens, with a 1M-token context from midtraining. Reflection pitches efficiency, not a capability crown. On its own tables Beam sits near GLM-5.2 on several coding and agentic tests and behind GLM-5.3 and Kimi K3 on most shared tasks. Weights, a technical report and a model card are due later this month under Apache 2.0. Early access is waitlist-only while final red-teaming finishes.
What Reflection shipped#
Pretraining finished in under four weeks on 6,144 Nvidia GB300 GPUs. The high-compute RL campaign used 10.5K GB300s for four weeks — Reflection says over 100 million rollouts and roughly 1.3 billion sandboxes. Beam remains text-only; Thinking Machines Lab’s Inkling is multimodal, so head-to-head coding wins in Reflection’s tables are not a full product comparison.
Sample self-reported scores (Reflection’s table; competitor numbers attributed via Artificial Analysis / DataCurve where Reflection cites them; vendor-compiled, so harnesses may differ):
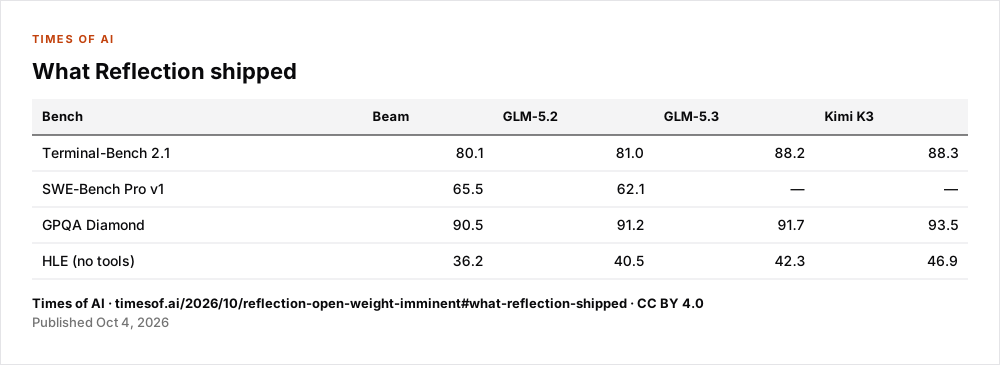
| Bench | Beam | GLM-5.2 | GLM-5.3 | Kimi K3 |
|---|---|---|---|---|
| Terminal-Bench 2.1 | 80.1 | 81.0 | 88.2 | 88.3 |
| SWE-Bench Pro v1 | 65.5 | 62.1 | — | — |
| GPQA Diamond | 90.5 | 91.2 | 91.7 | 93.5 |
| HLE (no tools) | 36.2 | 40.5 | 42.3 | 46.9 |
Reflection says Beam is “approaching Qwen 3.8-Max” and that Kimi K3 remains ahead on raw capability. The 3–4× less inference compute claim versus GLM-5.2-class reasoning is Reflection’s estimate: FLOPs ≈ 2 × active parameters × mean generated tokens, counting multiply-add as two ops. The company notes the estimate excludes prompt prefill, context-dependent attention and serving overhead — approximate compute comparison, not measured serving cost.
Money and the factory pitch#
TechCrunch (Rebecca Bellan, Oct. 5) says Reflection has raised about $4.7 billion (PitchBook) at a $25 billion pre-money valuation, and has over $7 billion in compute deals with SpaceX and Nebius for Nvidia GB300 access through 2029. That supersedes Axios’s adjective-only “massive” Nebius/SpaceX compute line from Oct. 4. The commercial frame is unchanged: sovereign AI factories that train Reflection weights on a buyer’s data and compute — with a Shinsegae pilot already announced in South Korea.
Claims vs checks#
All benches above are vendor-reported. TechCrunch notes the claims are not independently verified. Until weights and third-party evals land, this is a scorecard with a release promise, sold on efficiency rather than a lead.
Limits#
- Benchmarks and the 3–4× compute claim are Reflection’s. Competitor scores in Reflection’s tables are sourced from AA/DataCurve per Reflection, not re-run here.
- Weights are not public. Apache 2.0 release is “later this month,” not a dated GA.
- Funding and compute-deal figures follow TechCrunch / PitchBook wording; outside dollar figures that conflict with that wording are not used.
- Beam is text-only; multimodal peers are not like-for-like.
- AA Intelligence Index: Beam not listed as of Oct. 6.
Sources#
- Reflection AI: Introducing Beam: Reflection’s 501B open-weight model (October 5, 2026)
- TechCrunch: Reflection debuts Beam, an open-weight AI model to rival Chinese models at lower compute cost (October 5, 2026)
- Axios: Scoop: Powerful open model is set to shake up AI race (Bradley Olson, October 4, 2026)